Skip to navigation

Building your first app with App Configuration

Follow a step-by-step walkthrough for building a Benchling App that uses App Configuration. This guide shows how to define configuration, connect it to your app logic, and test the resulting behavior.

For this tutorial we’ll use the simple app from Building your first Benchling App. To review, that app updates the “Species” field for all DNA sequences of a certain schema. The full code is included here for reference:

from benchling_sdk.benchling import Benchling
from benchling_sdk.models import DnaSequenceBulkUpdate, AsyncTaskStatus
from benchling_sdk.auth.client_credentials_oauth2 import ClientCredentialsOAuth2
from benchling_sdk.helpers.serialization_helpers import fields
from datetime import datetime, timedelta
import random
tenant_name = "Your tenant"
client_id = "Your app's Client ID"
client_secret = "Your app's client secret"
auth_method = ClientCredentialsOAuth2(
client_id=client_id,
client_secret=client_secret,
token_url=f"https://{tenant_name}.benchling.com/oauth/token")
benchling = Benchling(url=f"https://{tenant_name}.benchling.com", auth_method=auth_method)
# Update this value to specify which schema this script will poll
entity_schema_to_check = "ts_AcqPy93F"
# Generates yesterday's date as a string formatted YYYY-MM-DD
today = datetime.today().date()
yesterday = today - timedelta(days=1)
time_string = f"> {yesterday.strftime('%Y-%m-%d')}"
species_list = ["Human", "Mouse", "Rat", "Camel"]
# Creates a generator returning DNA sequences matching the filter params
dna_sequences_list = benchling.dna_sequences.list(
modified_at=time_string,
schema_id=entity_schema_to_check,
page_size=100,
)
def update_species_bulk(sequence_pages):
# Loop through the pages provided by the generator, updating Species as required
for page in sequence_pages:
updates = []
for sequence in page:
current_species = sequence.fields["Species"].value
if not current_species:
species_to_add = random.choices(species_list)[0]
update = DnaSequenceBulkUpdate(
id=sequence.id,
fields=fields(
{
"Species": {"value": species_to_add}
}
)
)
updates.append(update)
if updates:
# Calls the bulk update API and returns an AsyncTask we need to poll
update_task_link = benchling.dna_sequences.bulk_update(updates)
# Polls every 1 second up to 30 seconds by default to see if it completes
update_task = benchling.tasks.wait_for_task(update_task_link.task_id)
if update_task.status != AsyncTaskStatus.SUCCEEDED:
raise RuntimeError(
f"Failed to update entities. Task ID: {update_task_link.task_id}\n"
f"Error: {update_task.errors}"
)
print("Completed bulk update for task", update_task_link.task_id)
else:
print("No entities found to update")
update_species_bulk(dna_sequences_list)

What happens if you try to install and run this app on a different Benchling tenant? Two lines cause problems:

  1. entity_schema_to_check = "ts_AcqPy93F" hardcodes a tenant-unique ID for the entity schema. A user installing this app on a different tenant will have a different ID value, and might have an entirely different type of schema whose “Species” field they want autofilled.
  2. current_species = sequence.fields["Species"].value references a schema field named “Species” exactly. On another tenant the field names are unlikely to match. The field might be called “Organism” instead.

An app manifest lets us remove both tenant-specific dependencies. First, create a YAML file with a manifest that includes configuration options to capture these details:

manifest.yaml
manifestVersion: 1
info:
name: My App Name
description: A user understandable description of what the app does, and support contact info.
configuration:
- name: DNA Sequence Schema
description: Select a DNA sequence schema with a species field for this app to autofill
type: entity_schema
fieldDefinitions:
- name: Species
description: Field that the app will write the species into.

This defines two configuration options: a field of type entity_schema, and a field named Species on that schema. The goal is to reference these instead of tenant-specific identifiers, so Benchling users can supply the correct values themselves. To do that, we install the app using this manifest:
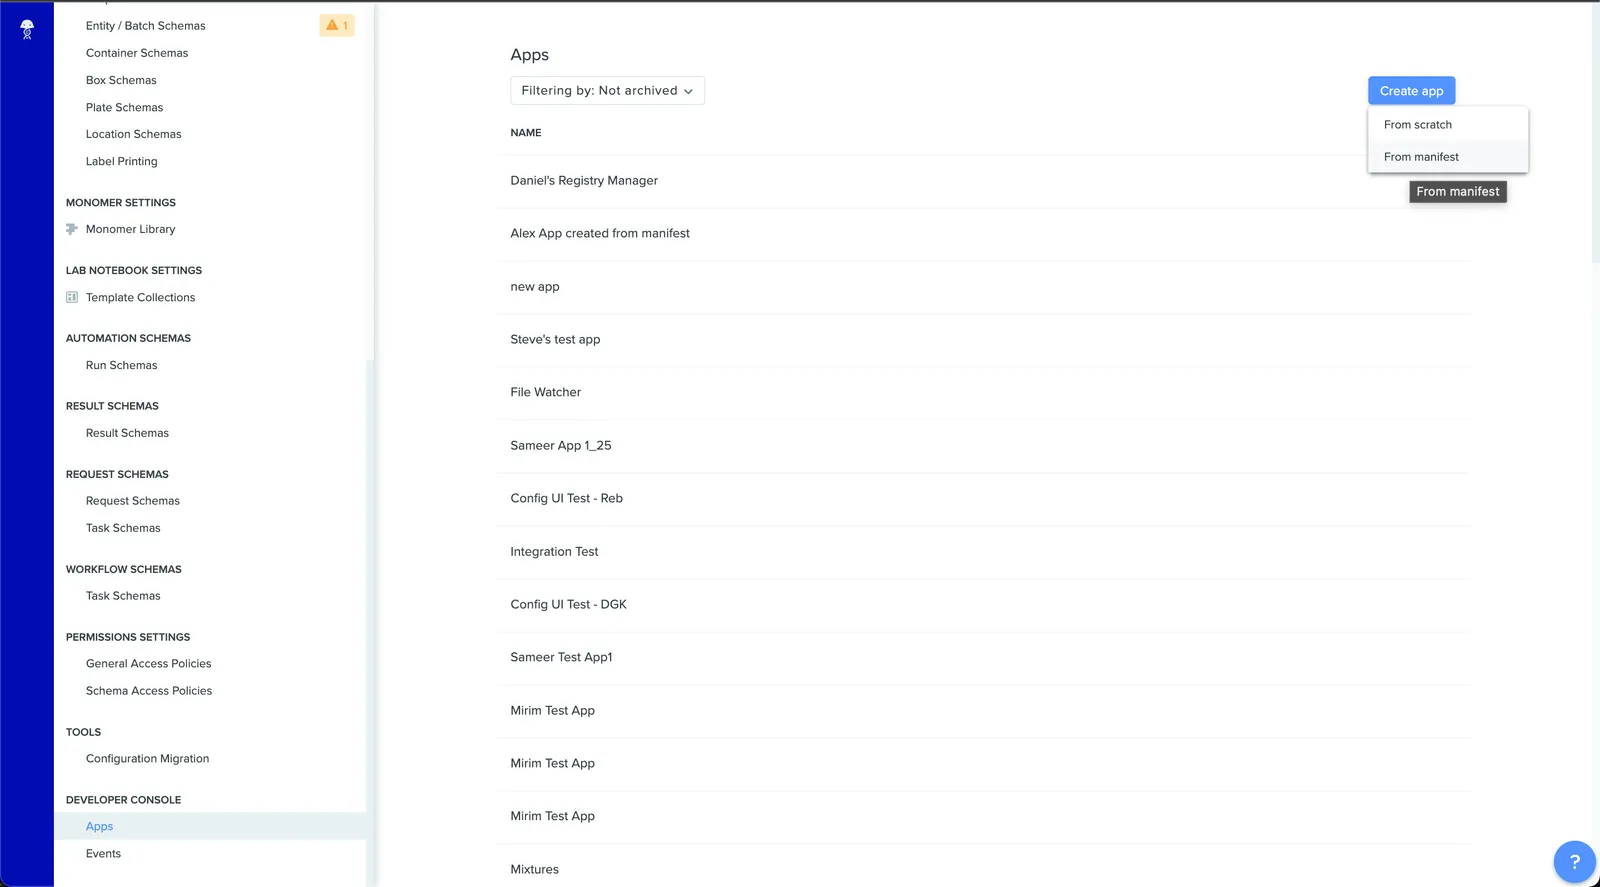
The Benchling App Workspace listing installed apps
The Benchling App Workspace
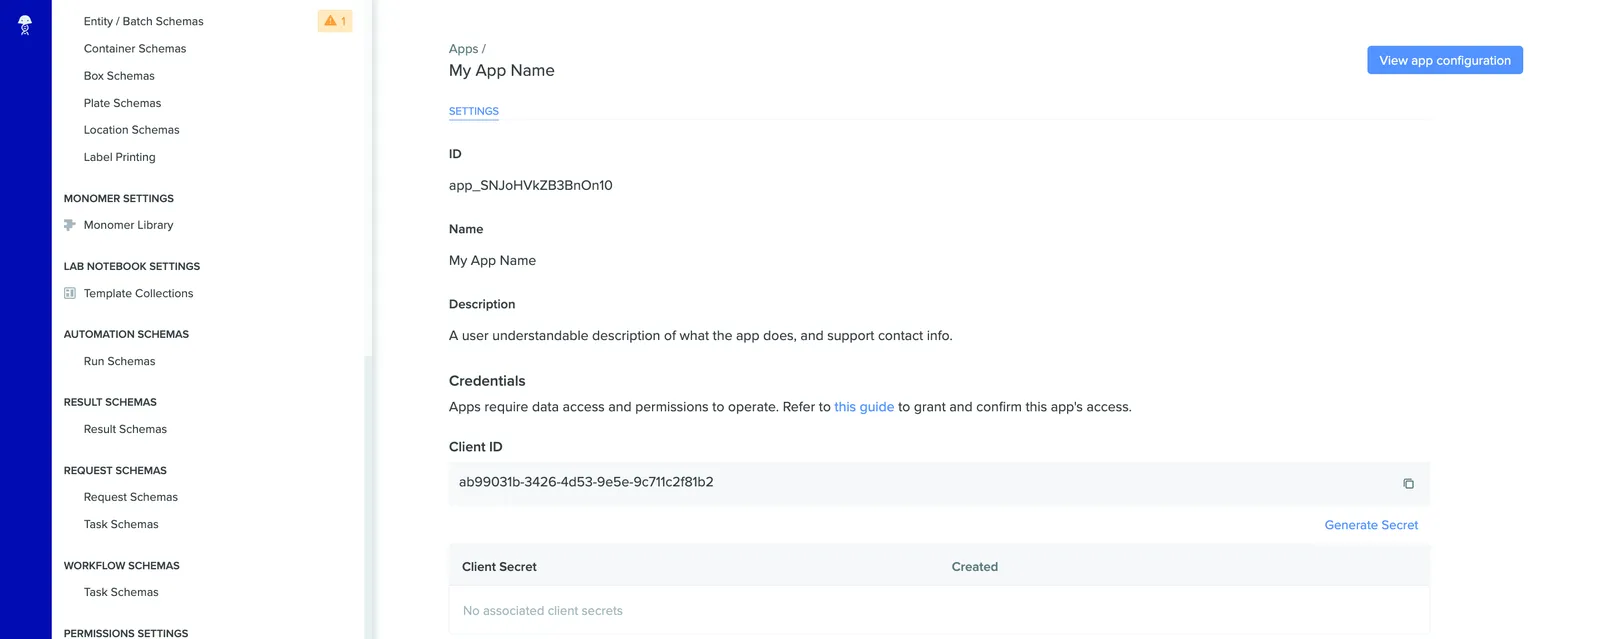
The settings page for an example Benchling App
The app settings page for an example app

With the app created from the manifest, follow the steps in Managing and Sharing Benchling Apps to complete the installation. Then finish configuring the app: click the “Connections” sidebar option, then the “Apps” tab, then “My App Name”, then the “Configuration” tab.
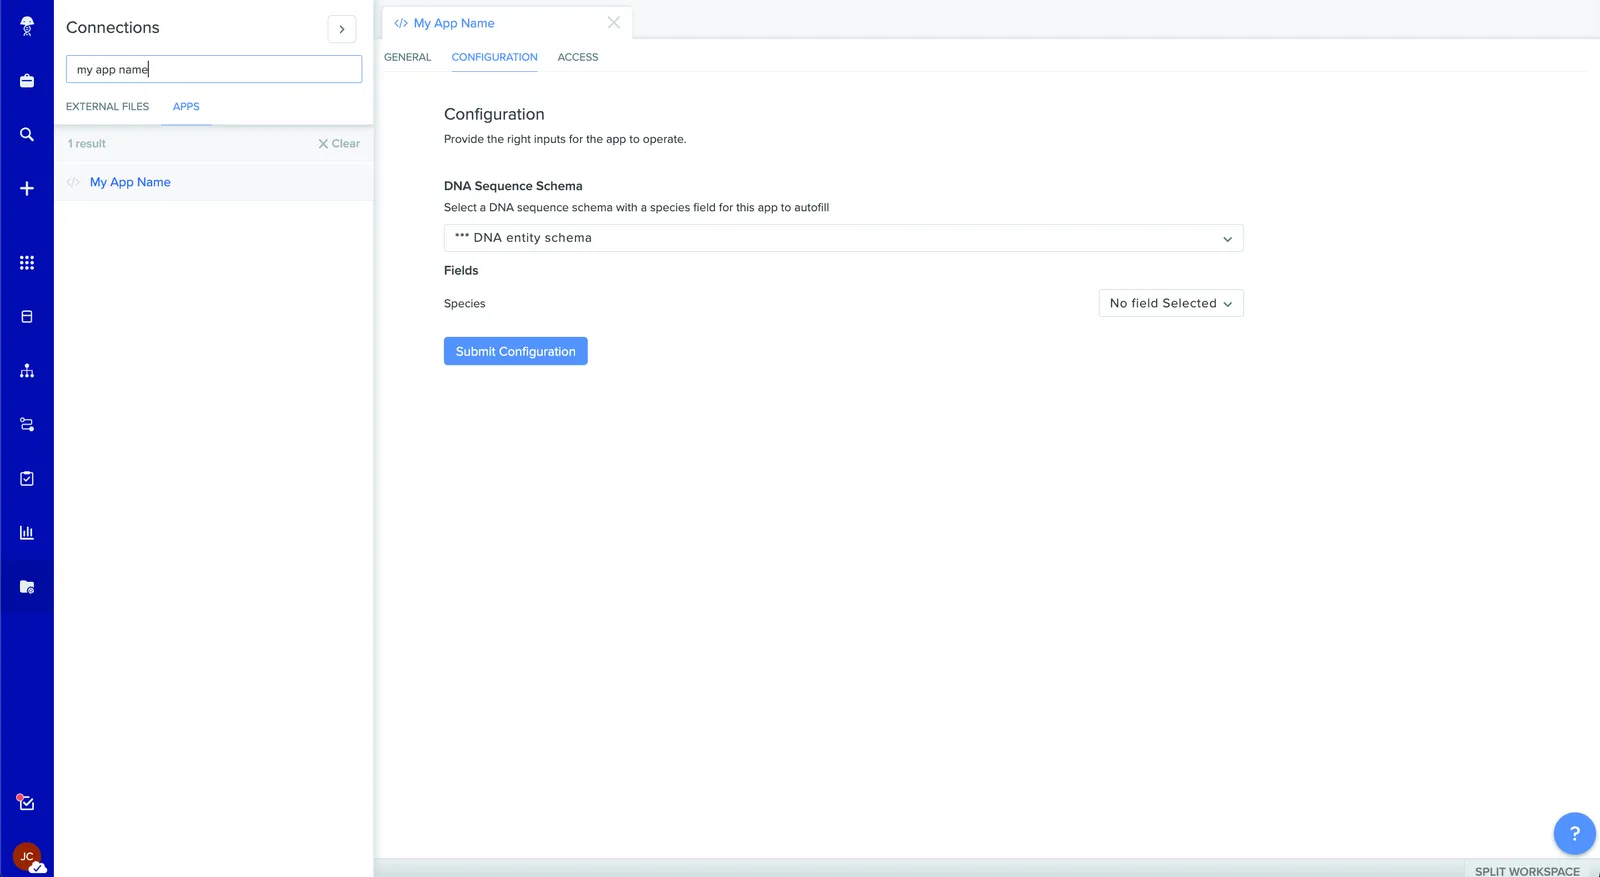
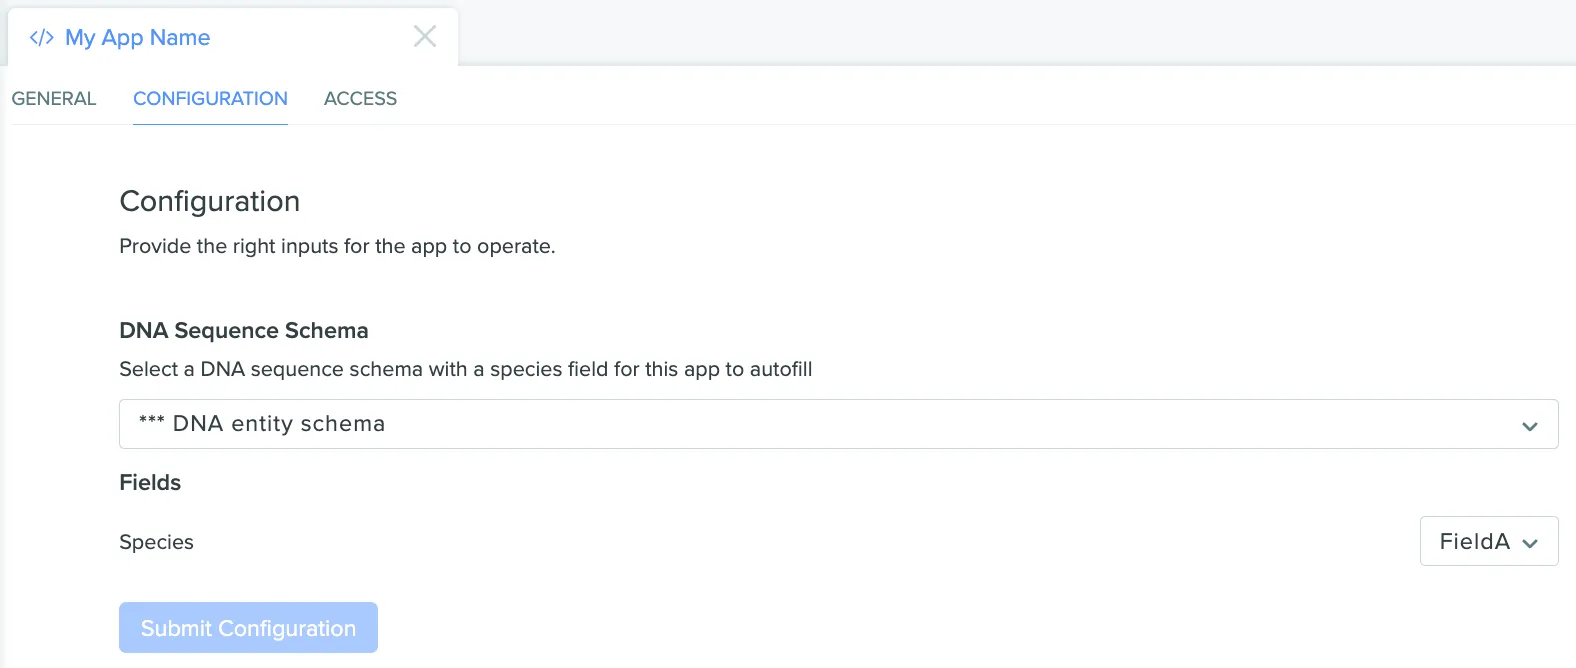
An app's Configuration tab showing the DNA Sequence Schema and Species fields from the manifest
The app configuration page showing our configuration fields

Our schema configuration options, defined in the app manifest, are configurable from this page. Select the schema on this tenant that the app should interact with:
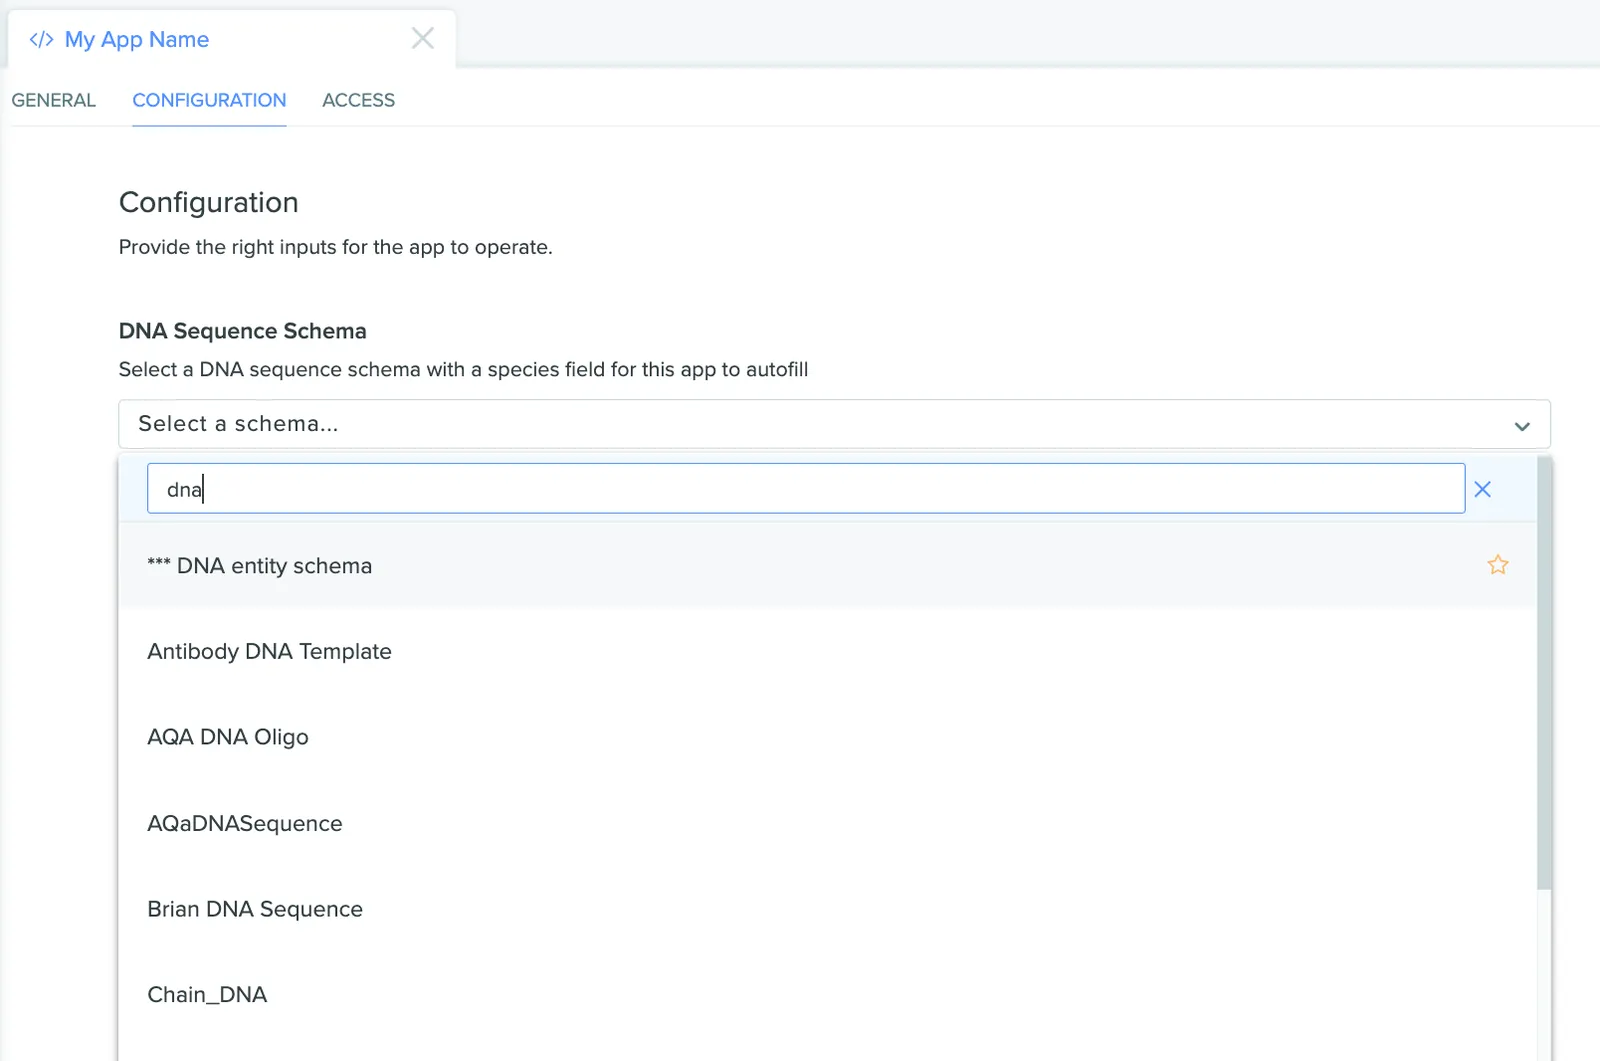
The app configuration page with an open dropdown menu of entity schemas
The app configuration page with an open dropdown listing selectable entities

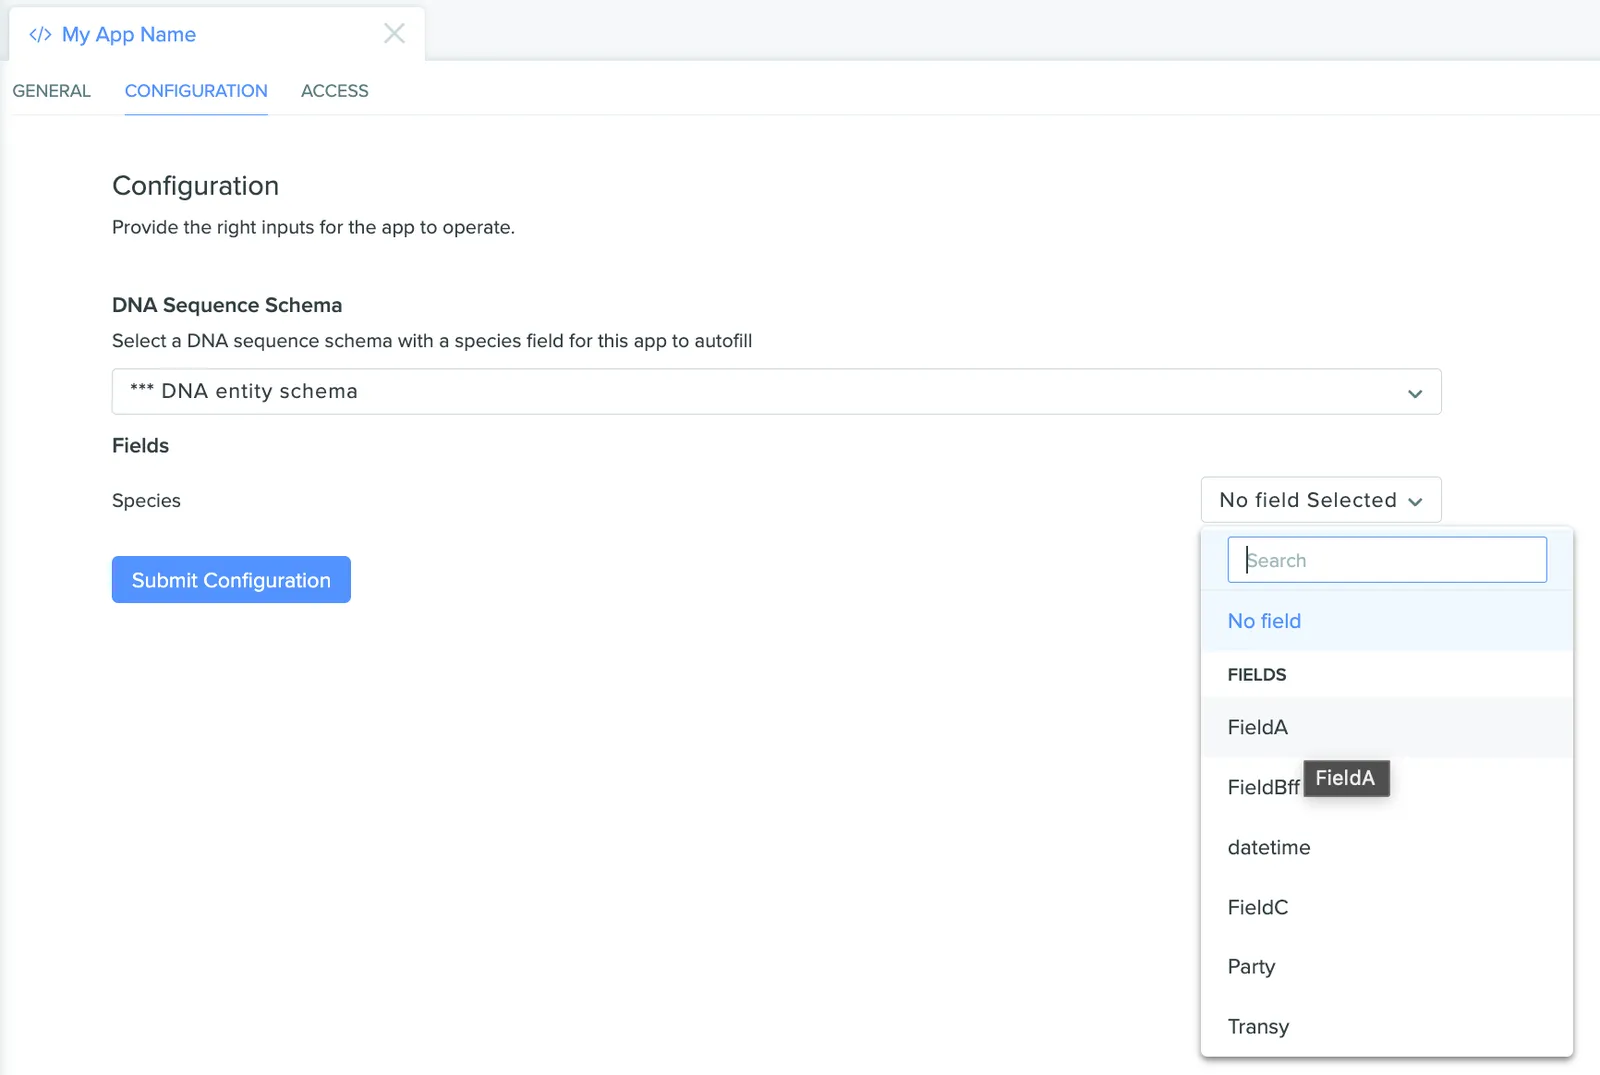
Once the schema is selected, choose the field on that schema the app should use, then submit the configuration:
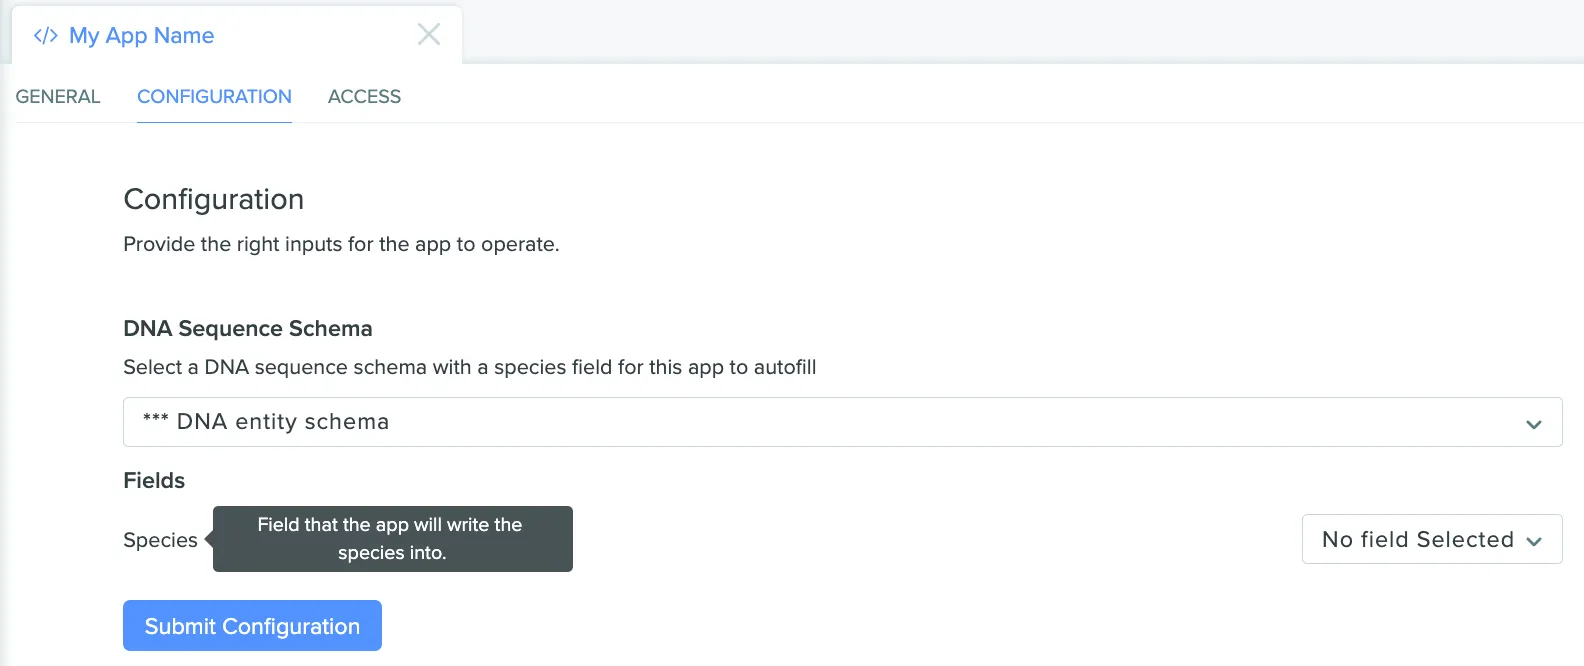
The app configuration page showing a selected entity schema and an empty Fields selector
The selected entity schema, with an additional 'Fields' selector
The app configuration page with the Fields selector dropdown open
The 'Fields' selector with an open dropdown listing options
The app configuration page showing both the entity schema and field selected
The selected entity schema and the selected field

We’re doing this ourselves for the tutorial, but the power of App Configuration is that a tenant admin can perform these steps themselves, which is what lets you build tenant-agnostic apps installable by multiple customers.

Updating app code to use configuration

The example app has its tenant URL, credentials, and app ID hardcoded as variables for demonstration purposes. This isn’t a best practice: using App Configuration requires storing these in a secure parameter store accessible by your app. We’ve omitted the details of that process here, since it’s specific to your app’s deployment environment.

Using the app’s credentials, app ID, and tenant URL, apps can read their own configuration through the Get app configuration items endpoint. The response looks like this:

Reading app configuration in V3

V3 is the recommended API for new development. It exposes app configuration read-only, as app config values rather than configuration items: GET /api/v3/app-config-value/items and GET /api/v3/app-config-value/{app_config_value_id}. Each value carries a path locating it in the configuration hierarchy and a valueData holding the value itself, typed by the app’s config spec. That is a different shape from the V2 response below, not a renamed one.

There is no V3 write path for app configuration, so anything that sets a config value stays on V2. The examples on this page are V2 throughout.

{
"appConfigurationItems": [
{
"apiURL": "https://piproduct.benchling.com/api/v2/app-configuration-items/aci_ksU0sJ8w",
"app": {
"id": "app_kcWboNOQCnKjFfGQ"
},
"description": "Select a DNA sequence schema with a species field for this app to autofill",
"id": "aci_ksU0sJ8w",
"linkedResource": {
"id": "ts_R3UNHyel",
"name": "*** DNA entity schema"
},
"modifiedAt": "2022-10-25T22:58:12.793897+00:00",
"path": [
"DNA Sequence Schema"
],
"requiredConfig": false,
"type": "entity_schema",
"value": "tsf_AnUZB7nO"
},
{
"apiURL": "https://piproduct.benchling.com/api/v2/app-configuration-items/aci_yM8hXMed",
"app": {
"id": "app_kcWboNOQCnKjFfGQ"
},
"description": "Field that the app will write the species into.",
"id": "aci_yM8hXMed",
"linkedResource": {
"id": "tsf_kng5zz63",
"name": "Species"
},
"modifiedAt": "2022-10-25T22:58:12.793897+00:00",
"path": [
"DNA Sequence Schema",
"Species"
],
"requiredConfig": false,
"type": "field",
"value": "tsf_AnUZB7nO"
}
],
"nextToken": ""
}

The top-level appConfigurationItems is an array of objects corresponding to all configuration options, each including metadata and the value selected by the tenant admin. We’re specifically interested in linkedResource, an object holding the API ID and name values we had previously hardcoded. We can update the app to pull this configuration dynamically at startup:

from benchling_sdk.benchling import Benchling
from benchling_sdk.models import DnaSequenceBulkUpdate, AsyncTaskStatus
from benchling_sdk.auth.client_credentials_oauth2 import ClientCredentialsOAuth2
from benchling_sdk.helpers.serialization_helpers import fields
from datetime import datetime, timedelta
import random
tenant_name = "Your tenant"
client_id = "Your app's Client ID"
client_secret = "Your app's client secret"
auth_method = ClientCredentialsOAuth2(
client_id=client_id,
client_secret=client_secret,
token_url=f"https://{tenant_name}.benchling.com/oauth/token")
benchling = Benchling(url=f"https://{tenant_name}.benchling.com", auth_method=auth_method)
# Pull the app config. First, define the variables we care about.
entity_schema_to_check = ""
species_schema_field_name = ""
# list_app_configuration_items() returns a page iterator, so cast it to a list
# to get all pages up front.
config_pages = list(
benchling.apps.list_app_configuration_items(app_id="app_kcWboNOQCnKjFfGQ")
)
# Iterate through all pages and config items
for page in config_pages:
for item in page:
# Marshal the path property into a tuple for comparison
path = tuple(item.path)
# Store the relevant IDs in our previously defined variables
if path == ("DNA Sequence Schema",):
entity_schema_to_check = item.linked_resource.id
if path == ("DNA Sequence Schema", "Species"):
species_schema_field_name = item.linked_resource.name
# Generates yesterday's date as a string formatted YYYY-MM-DD
today = datetime.today().date()
yesterday = today - timedelta(days=1)
time_string = f"> {yesterday.strftime('%Y-%m-%d')}"
species_list = ["Human", "Mouse", "Rat", "Camel"]
# Creates a generator returning DNA sequences matching the filter params
dna_sequences_list = benchling.dna_sequences.list(
modified_at=time_string,
schema_id=entity_schema_to_check,
page_size=100,
)
def update_species_bulk(sequence_pages):
# Loop through the pages provided by the generator, updating Species as required
for page in sequence_pages:
updates = []
for sequence in page:
current_species = sequence.fields[species_schema_field_name].value
if not current_species:
species_to_add = random.choices(species_list)[0]
update = DnaSequenceBulkUpdate(
id=sequence.id,
fields=fields(
{
species_schema_field_name: {"value": species_to_add}
}
)
)
updates.append(update)
if updates:
# Calls the bulk update API and returns an AsyncTask we need to poll
update_task_link = benchling.dna_sequences.bulk_update(updates)
# Polls every 1 second up to 30 seconds by default to see if it completes
update_task = benchling.tasks.wait_for_task(update_task_link.task_id)
if update_task.status != AsyncTaskStatus.SUCCEEDED:
raise RuntimeError(
f"Failed to update entities. Task ID: {update_task_link.task_id}\n"
f"Error: {update_task.errors}"
)
print("Completed bulk update for task", update_task_link.task_id)
else:
print("No entities found to update")
update_species_bulk(dna_sequences_list)

Both original problems are now resolved:

  • dna_sequences.list(..., schema_id=entity_schema_to_check) uses the resource ID from App Configuration instead of a hardcoded ID value.
  • sequence.fields[species_schema_field_name].value depends on the field listed in App Configuration instead of the hardcoded name "Species".

These changes let the app be installed and configured on any Benchling tenant without code changes. Users can also rename fields and change schemas without affecting the app’s functionality, as long as they update the corresponding values in App Configuration.

Each app configuration item also includes other metadata like id and apiURL. In future guides we’ll cover best practices for interacting with app configuration options in a more abstract way.