

Getting Started with the Warehouse
The data warehouse is a read-only SQL database that tracks assay data, biological
entities, inventory data, notebook entries, and other records stored in Benchling. The
warehouse centralizes the entire organization’s research output and makes it possible
to run queries that would historically require parsing multiple data sources, such as
“find all batches that had an OD > 1000”.
The warehouse is well-suited to complex analytics, where the expressiveness of SQL matters. It can be securely connected to third-party analytics tools such as Tableau and Spotfire to create charts and dashboards backed by Benchling data. Configurable permissions ensure appropriate data access control.
All the data the warehouse stores, and the tables it is stored in, are outlined in Warehouse Tables.
How it works
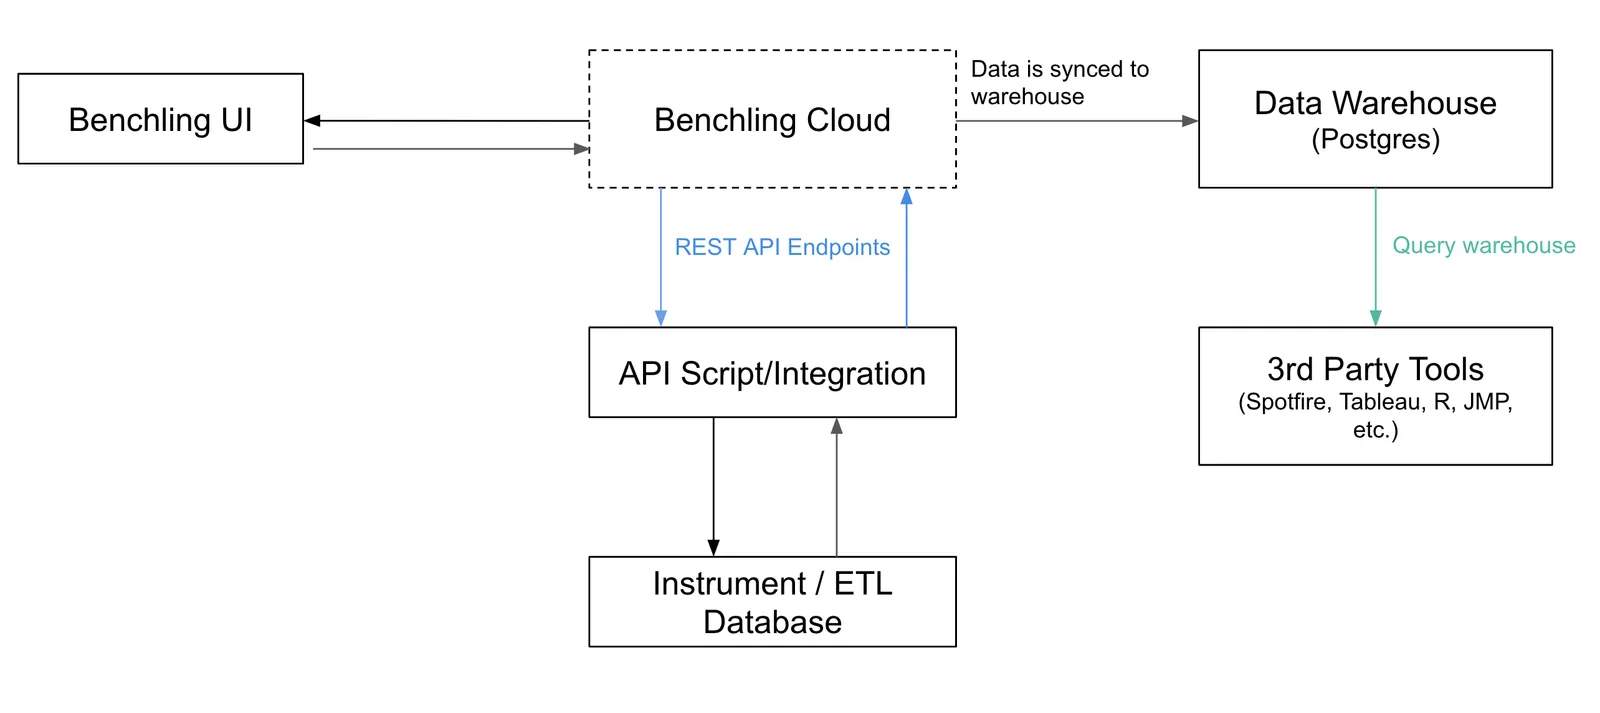
The warehouse ingests both user-generated data about entities from the registry and assay results from networked instruments. To enable this aggregation, it works as follows:
- Researchers register new samples in the registry, specifying properties about the sample. A T cell receptor, for example, may capture information about the Alpha chain, Beta chain, and Specificity.
- They initiate a new run, specifying the assay to be run, the sample IDs, and parameters such as the adapter used.
- Results from the assay are uploaded as structured data and blobs to the warehouse.
- Third-party analysis and visualization tools connect to the warehouse to consume the data.
When can I expect data to sync to the warehouse?
Generally, data uploaded to Benchling syncs to the data warehouse within 24 hours. Shorter tasks like entity and results uploads with fewer than 1000 rows are often synced within minutes, depending on the total activity in your Benchling tenant. Larger uploads take longer, such as registry or results uploads with more than 1000 rows, and large API integrations.
Don’t worry if you don’t see your data appear in the warehouse until the next day. If you need your data in real time, consider using the REST API to upload or access it.
Obtaining credentials
Warehouse credentials are obtained from the Account Settings page in Benchling. Generate new credentials by clicking “Create credentials” under the Warehouse credentials section. If you don’t see this option, contact your Benchling Customer Success Manager to enable access on your account.
Protecting your warehouse credentials
Warehouse credentials can be used to gain direct access to your Benchling data. These credentials are static and can be used by anyone, anywhere, so it’s critical to keep them secure. We recommend keeping your warehouse username and password in your password manager or similar secure storage.
Warehouse credentials should not be hard-coded into scripts or checked into source control. If your warehouse credentials are leaked, revoke them immediately and generate new ones from your profile settings screen in Benchling.
Warehouse configuration
The Benchling Data Warehouse is a hosted PostgreSQL solution. Any client, tool, or system that can connect to a PostgreSQL server can connect to your warehouse. Connections must be made with SSL/TLS; plaintext (unencrypted) connections are not supported.
What is SSL/TLS?
In short: SSL/TLS ensures that nobody can read or tamper with your data while it travels over the internet to your warehouse. You’re using it right now to read this document in your web browser, and it can also be used for databases.
Here’s a short explanation and a longer one that defines other important SSL/TLS terms.
Security notice: SSL/TLS and PostgreSQL
Many
PostgreSQL clients do not by default properly encrypt connections to the database.
This includes common tools like psql and libpq-based libraries like Python’s
psycopg2. Incorrect configuration puts your data and credentials at risk of an
interception attack by a network adversary. Don’t assume it works the same way as
HTTPS in your browser.
Our warehouse server is set to only allow TLS connections (specifically TLS 1.2+). But due to nuances in the PostgreSQL network protocol, namely the documented but obscure default fallback-to-plaintext behavior, security ultimately depends on you and the software you connect to your warehouse.
Be sure to explicitly enable SSL/TLS in your PostgreSQL client. A correct defense must include root Certificate Authority (CA) verification at a minimum. See below for some common cases.
Configuring PostgreSQL clients for security
The instructions here set the per-user default, and work with Python’s psycopg2 and
the JDBC PostgreSQL driver in addition to psql. If
they don’t work for you, or you need to connect to many PostgreSQL servers, refer to
the official psql and
libpq SSL documentation.
Choosing the correct certificate bundle
The following instructions set up your warehouse connection to trust the global AWS RDS certificate bundle. If you prefer, you can use one of the more specific RDS Root CA alternatives. These certificates rotate every few years, so they may need an update if you start getting a connection error.
On macOS and Linux
Set up the ~/.postgresql/root.crt file to hold the RDS certificate bundle. Open a
terminal and run the following (this assumes you’re using bash as your shell and don’t
already have a root.crt file):
On Windows
Set up the %APPDATA%\postgresql\root.crt file to hold the RDS certificate bundle.
- Download
the global RDS certificate bundle
to your Downloads folder and open that folder. You should see a new file named, for
example,
global-bundle.pem. - Open a second File Explorer window (Ctrl+N, or File > New Window) and type
%APPDATA%in its address bar. - If you see a folder called
postgresql, open it. If not, create a new folder named exactly that and open it. If you can’t see or create this folder, contact your IT team. - Drag the downloaded
global-bundle.pemfrom Downloads into thepostgresqlfolder. - Rename
global-bundle.pemtoroot.crtto set it as the default (recommended). Ifroot.crtalready exists, appendglobal-bundle.pemto it instead.
We also highly recommend setting the PGSSLMODE environment variable to verify-ca
(Win+X > System > Advanced System Settings > Advanced tab > Environment Variables). If
you are a Windows IT administrator with Group Policy access, we highly recommend
setting this variable and PGSSLROOTCERT to the location of a shared CA certificate
file for all users.
Advanced configuration and considerations
Secure connections must set at least the verify-ca SSL mode. Use either the
PGSSLMODE
environment variable or
the equivalent
sslmode parameter.
Without it, a network attacker could spoof the identity of the warehouse PostgreSQL
server with a fake certificate and steal everything you have access to.
To set an alternative location for the root CA certificate, set the PGSSLROOTCERT
environment variable or
the equivalent
sslrootcert parameter
to the path of the file. Note that ~/.postgresql/root.crt (and its Windows
equivalent) can contain multiple certificates if you need to connect to and trust
multiple PostgreSQL servers; just append the additional PEM-formatted certificates to
the file.
The verify-full mode is supported for extra security, but you may need to adjust your
connection hostname to “pin” it to the actual RDS Aurora PostgreSQL instance. To find
the real instance name behind your friendly name, for example
postgres-warehouse.examplename.benchling.com, use DNS tools or a site like
nslookup.io to find the CNAME for the alias Benchling provided. Be aware that
Benchling may need to migrate your data to meet certain performance guarantees, so this
pinned hostname may change. AWS’s
SSL/TLS configuration advice for Aurora PostgreSQL
has more detail.
Connecting with psql
SSL/TLS and psql
Without the sslmode parameter or the PGSSLMODE environment variable,
psql defaults to “prefer” SSL mode,
which is vulnerable to eavesdropping and machine-in-the-middle attacks. See above
for more details.
To connect to your warehouse, run the following, replacing yourusername and yourdeployname with your individual settings:
This prompts for your password. Be sure to use single quotes so the $ isn’t
interpolated as a shell variable.
Connecting using JDBC
The connection string for psql also works for Java JDBC connections:
Replace yourusername and yourdeployname with your individual settings.
The
PostgreSQL JDBC connector SslMode documentation
has more on the SSL/TLS settings. You will need to set up the correct RDS root
certificates, just as with the other tools above, possibly using Java’s keytool.
Connect using a third-party tool or SaaS
SSL/TLS and third-party SaaS
Many services require you to enable SSL or TLS to connect, and it’s very important that you do. Also enable the Root Certificate Authority (“root CA”) verification feature, or ask your SaaS vendor to support it.
To connect to the warehouse, use the following parameters in your data visualization tool:
- Host name:
postgres-warehouse.yourdeployname.benchling.com, replacingyourdeploynamewith your enterprise-specific domain (the part beforebenchling.comin your enterprise’s URL) - Port: 5432 (the default)
- Database:
warehouse - Username: the username you generated
- Password: the password you generated
- SSL or TLS mode: enabled. This is very important for your data security
- Root Certificate Authority / trusted certificate: download and upload the global RDS certificate bundle
Where possible, use the verify-ca SSL/TLS connection mode; it might be called
“check server certificate”. If the tool also asks for an SSL/TLS client certificate,
you can
generate your own.
Warehouse limits and best practices
For integrations that connect directly to the data warehouse, Benchling has established limits around concurrent connections and transaction duration. These limits ensure that updates can sync in a timely manner and that the warehouse is able to reliably serve queries.
They include limits on the number of concurrent connections per user and per tenant, as well as guidelines around polling frequency and transaction duration. The warehouse limits and best practices section of the Limits page has the specifics.
Example
Runs store parameters about the assay that will be performed, such as the instrument ID. Results capture results generated by the assay and associated with the samples, such as the cell count.
Scenario: capturing results from a flow cytometry run
Researchers configure schemas for the flow cytometer assay in the Benchling UI. They set up fields and specify each data type, such as string or float. Fields can be links to blobs, which handle raw data and images.
They then initiate the assay on the flow cytometer and upload parameters about the run, such as the instrument ID, to Benchling. An example run:
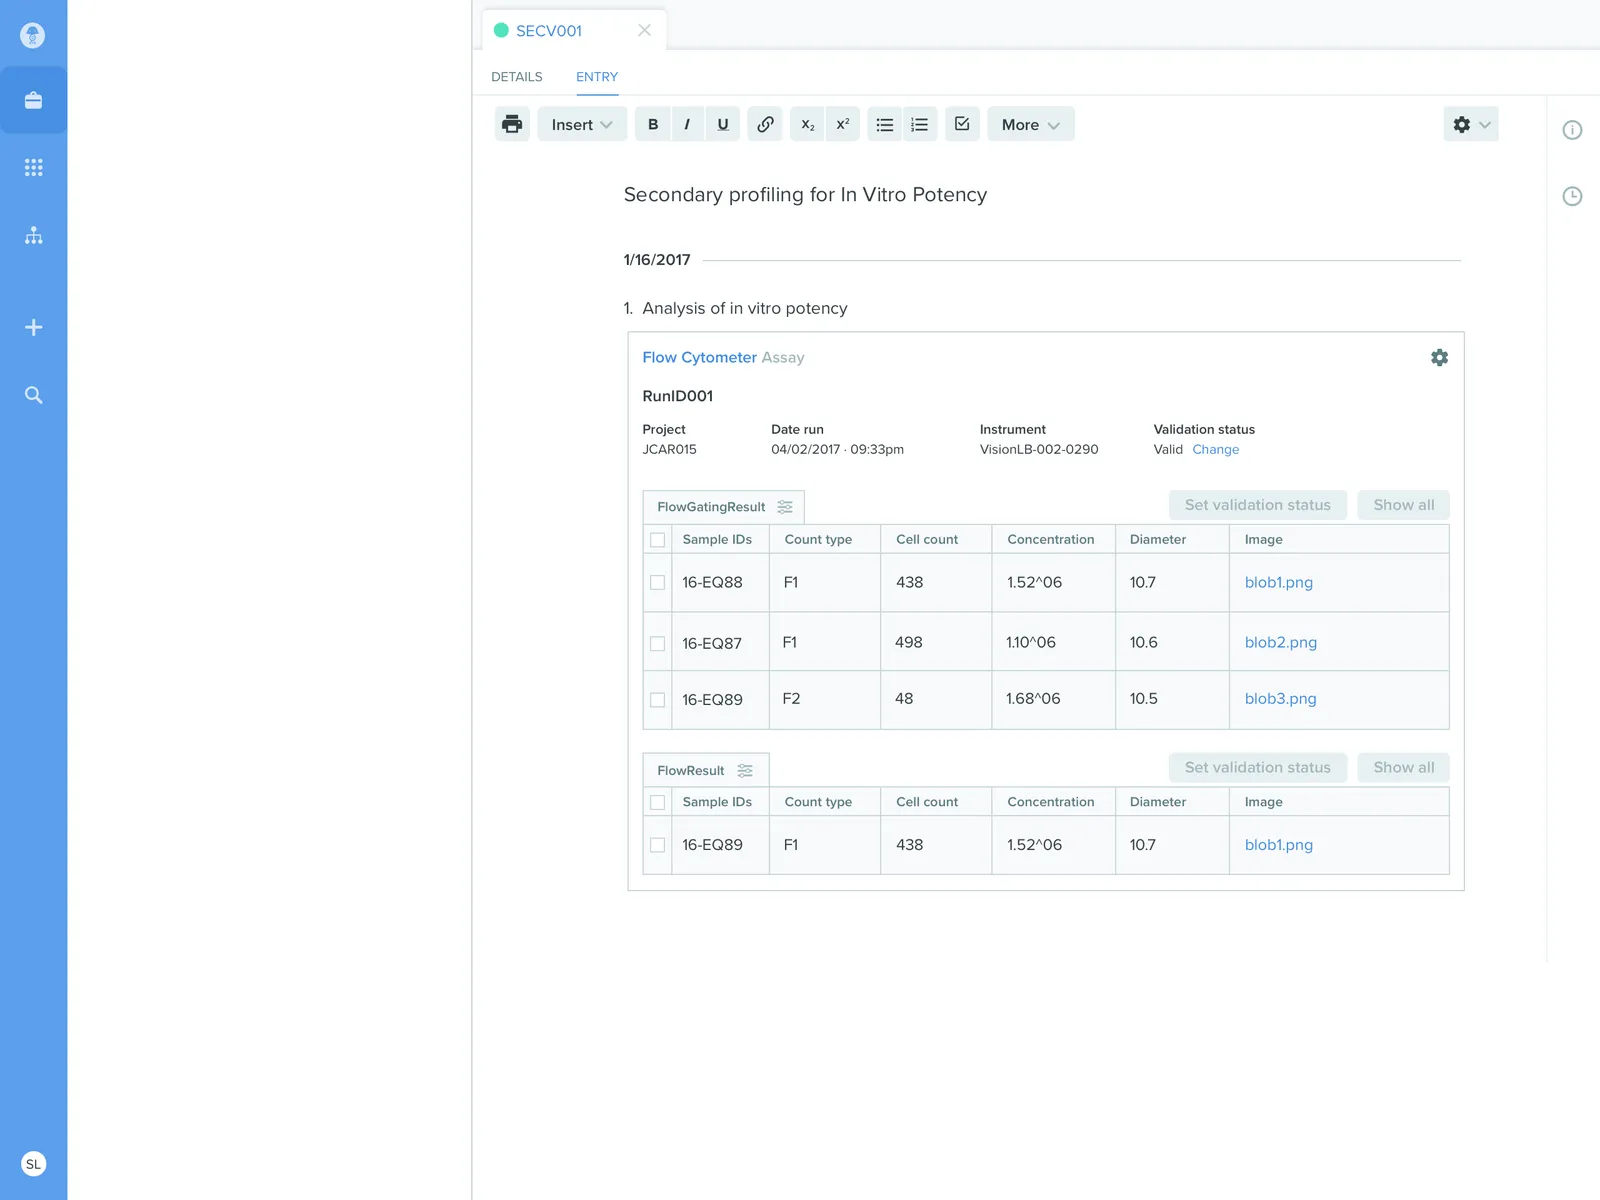
After the run completes, a script on the instrument uploads results to Benchling, specifying the sample and container they are associated with along with results such as the CD3+ values. An example result:
The run is attached directly to an ELN entry in Benchling:
When researchers want to analyze results across multiple runs, they query the warehouse using third-party analytics tools or SQL directly: