

Analyses API Developer Guide
The Analyses API includes a number of endpoints for working with the Benchling Analysis product. Integrators can use the import/export functionality of Benchling analyses to let users interact with external systems, pulling Benchling data out for external analysis and uploading post-analysis data files back in.
This guide walks through how Benchling users interact with the Analyses product, and how apps can extend an analysis through import/export. That includes the Analyses API endpoints in more detail, as well as core concepts such as analysis keys. Like most integrations, we recommend Analysis integrations use app authentication, so before working with the Analyses API make sure you’re familiar with building Benchling Apps.
This page uses V2 because the analysis write path is V2-only
V3 is the recommended API for new development, and it does expose analyses (GET /api/v3/analysis/items, GET /api/v3/analysis/{analysis_id}, GET /api/v3/data-frame/items, and the analysis template endpoints), but all of them are read-only. Patching an analysis and creating a data frame have no V3 equivalent, and the import/export flow below depends on both, so it stays on V2 end to end.
Use the V3 endpoints when you only need to read an analysis, its steps, or its data frames.
Getting started
Before diving in, it’s worth a closer look at how Benchling users create analyses to process their data. Benchling analyses include:
- Analysis object. Objects that let users view and analyze experimental result data
- Data frames. Tabular data used in analyses
- Files. Raw files (images, text, HTML)
Apps interact with analyses through the import/export feature, which lets an integration both export data frames from Benchling and import data frames and files into Benchling. To users, this all happens as part of a single action in their Benchling Analysis.
Analysis integration user flow
Users interact with import/export in the following way. First, a user copies the analysis key from the import/export dialog in Benchling. Next, they provide the key to the integration through an external UI. Finally, the user returns to the Benchling Analysis, where the external system has sent the data frame.
While the purpose of an Analysis integration is to process or analyze data on an external platform, the following components are also crucial:
- A UI for accepting an analysis key
- A mechanism for pulling data frames from Benchling
- A mechanism for pushing data frames and files to Benchling
Analysis key
An analysis key is a value provided to Benchling users when working with the
import/export feature. It is composed of the relevant analysis_id and a JSON Web
Token (JWT), separated by a colon (:). The analysis_id is the internal Benchling
identifier for the analysis, and the JWT can be used to authenticate requests to the
customer’s tenant.
Here’s an example key:
The JWTs associated with analysis keys expire after 10 minutes, after which users must generate a new one. A new key is generated each time a Benchling user copies one from the import/export dialog, so if you’re using the key to authenticate, be sure to prompt for a new key each time a user runs the external analysis.
While analysis keys include a JWT that can be used to authenticate requests, this is not a best practice. Analysis key authentication is fine for testing, but the 10-minute expiration makes it unsuitable for production applications. Consider creating a Benchling App and using app authentication instead.
The JWT payload portion of an analysis key contains information about the customer’s tenant, including a unique tenant identifier. This matters particularly when building multi-tenant apps. Here’s a Python example of working with analysis keys:
Downloading data frames from Benchling
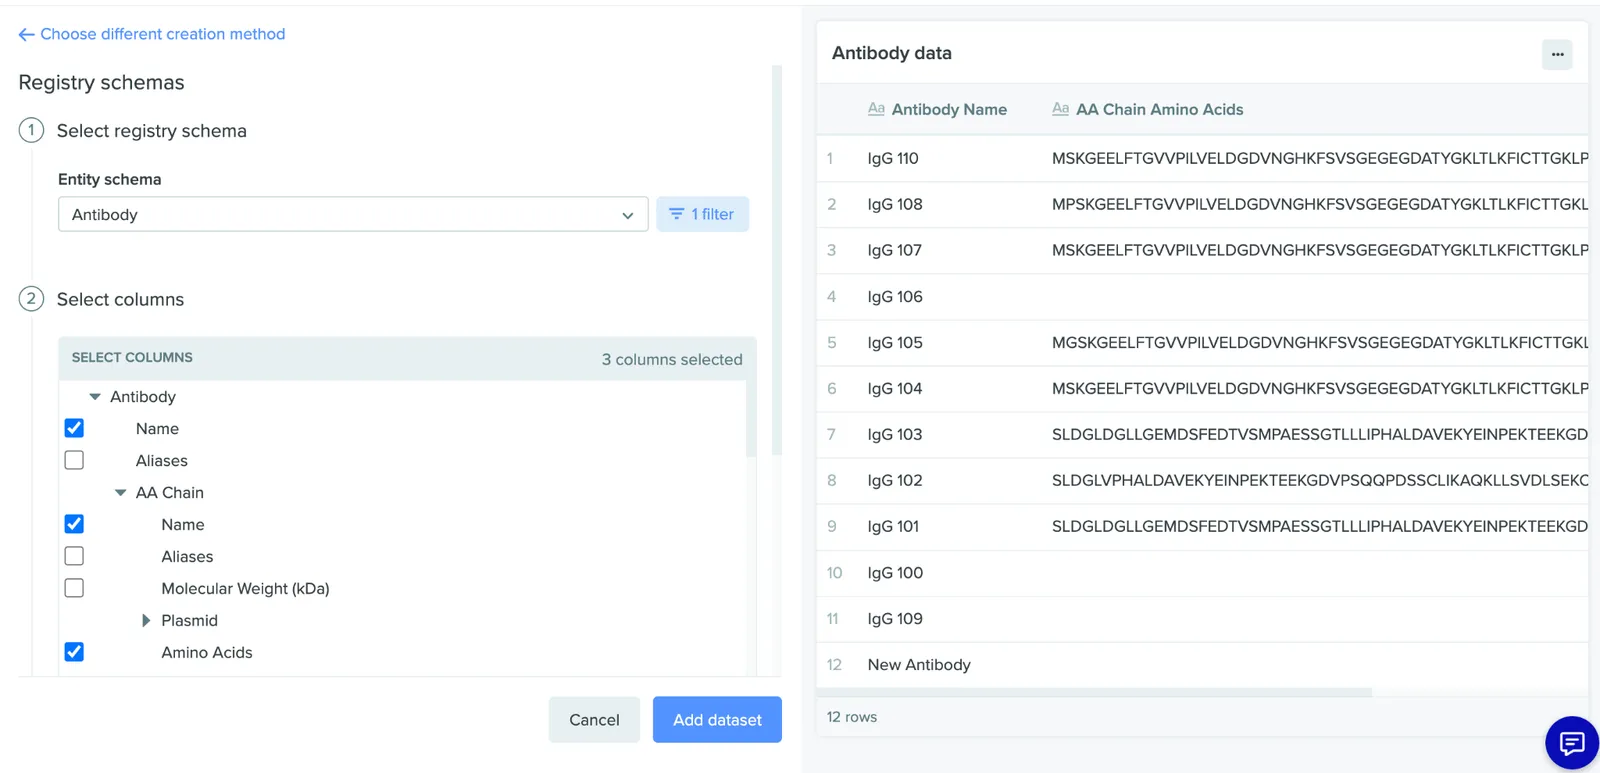
Users start an analysis by creating an initial data frame from registry data, from a dashboard query, or from existing tabular data. The Benchling Help Center has more on how users interact with the Registry and Insights tools.
This initial data frame is the foundation of the analysis, and the starting point for creating views and importing or exporting other files and data frames. Data frames are the main object analyses work with, and an analysis can work with multiple data frames at once.
Imports and exports begin with obtaining the relevant inputs. The Get an analysis
endpoint (GET /v2-beta/analyses/:analysis_id) returns an analysis object:
Note that there may be multiple data frames and files returned, since each analysis can have any number of them to download.
Data frame inputs
With a data frame ID from the dataframesIds array, query the Get a data frame
endpoint (GET /v2/data-frames/:dataframes_id) for the data frame’s metadata. Two
fields matter most:
uploadStatus: the current status of the data frame, one ofIN_PROGRESS,SUCCEEDED,FAILED_VALIDATION, orNOT_UPLOADED. For the purposes of getting an initial data frame, we’re only concerned withSUCCEEDED.manifest: a list of the files that make up the data frame, each represented by an object including the name and URL. The value of theurlfield varies with the data frame’suploadStatus:- For
SUCCEEDEDdata frames, it is the file’s download URL. - For
NOT_UPLOADEDdata frames, it is a pre-signed URL used to upload a file via the Update a data frame endpoint (PATCH /v2-beta/data-frames/{dataframes_id}). - For all other statuses,
urlisnull.
- For
For data frames with an uploadStatus of SUCCEEDED, the url fields are pre-signed
URLs that can be used to download the data frame CSV data. Here’s an example data
frame:
File inputs
Like data frame inputs, use the file IDs from the fileIds array to query the Get a
file endpoint (GET /v2/files/{file_id}) for metadata about the file:
Unlike data frame inputs, the response doesn’t contain a manifest field. Instead, a
Content-Location header includes the pre-signed URL where the file can be downloaded.
Uploading data frames and files to a Benchling Analysis
Once an integration has completed an external analysis, the final product is uploaded back to the Benchling Analysis. Both data frames (for tabular data) and files (for images or other file types) can be pushed back.
Pushing data back involves creating the data frame or file definition in Benchling, then uploading the relevant data to it.
Files must live in a folder
Files are first-class objects in Benchling, and therefore require a location when
they are created, which is what the required folderId parameter supplies. Usually, files are
created in the same folder as the associated analysis. The
Folders API has more on folders in
Benchling.
Importing new data frames to a Benchling Analysis
Create data frames using the Create a data frame endpoint (POST /v2/data-frames),
first specifying the data frame’s manifest, including the name of the data frame or
the file to be uploaded:
The response includes a complete data frame object with a status of NOT_UPLOADED; the
manifest now includes a pre-signed URL, and the object has a data frame ID:
Using the url, upload the CSV to Benchling. Include the
x-amz-server-side-encryption: AES256 header to work with Benchling’s server-side
encryption:
Finally, update the status of the data frame to IN_PROGRESS using the data frame ID
and the Update a data frame endpoint (PATCH /v2/data-frames/{dataframes_id}):
This endpoint is asynchronous; a successful request returns a 202 Accepted with an
empty response body and launches the process to validate and transform the uploaded CSV
into a data frame. Once complete, the data frame’s status is automatically updated to
SUCCEEDED or FAILED_VALIDATION.
Importing new files to a Benchling Analysis
File imports follow a nearly identical process, with a couple of differences. First,
create a file definition in Benchling using the Create a file endpoint
(POST /v2/files):
This creates the file definition, and as with data frames a file ID and pre-signed URL are returned:
Notably, the upload URL is not included in the response body. It is in the
Content-Location header instead. Upload the file to that URL, again including the
x-amz-server-side-encryption: AES256 header:
Finally, update the status of the file definition. Unlike data frames, files undergo no
validation or conversion, so the status can be set directly to SUCCEEDED:
Benchling supports a maximum file size of 30 MB. Currently supported file types are
.html, .jmp, .jrn, .jrp, .jpeg, .jpg, .png, .csv, and .txt.
End-to-end example
Here is the file and data frame upload process in Python:
Associating data frames and files to an analysis
Once data frames or files from an external analysis have been uploaded to Benchling,
they can be attached to the analysis. This means updating the analysis to include them
using the Update an analysis endpoint (PATCH /v2-beta/analyses/{analysis_id}).
Additional requests with data frames or files append the new objects to the analysis.
Attaching a data frame:
The same request in Python: